Meet the Author
Fred Hebert
Staff Site Reliability Engineer
Fred is a Staff Site Reliability Engineer (SRE) who has worked as a software engineer for over a decade and ended up with a healthy dislike of computers and clumsy automation. He’s a published technical author who loves distributed systems, systems engineering, and has a strong interest in resilience engineering and human factors.
Explore Author's Blog
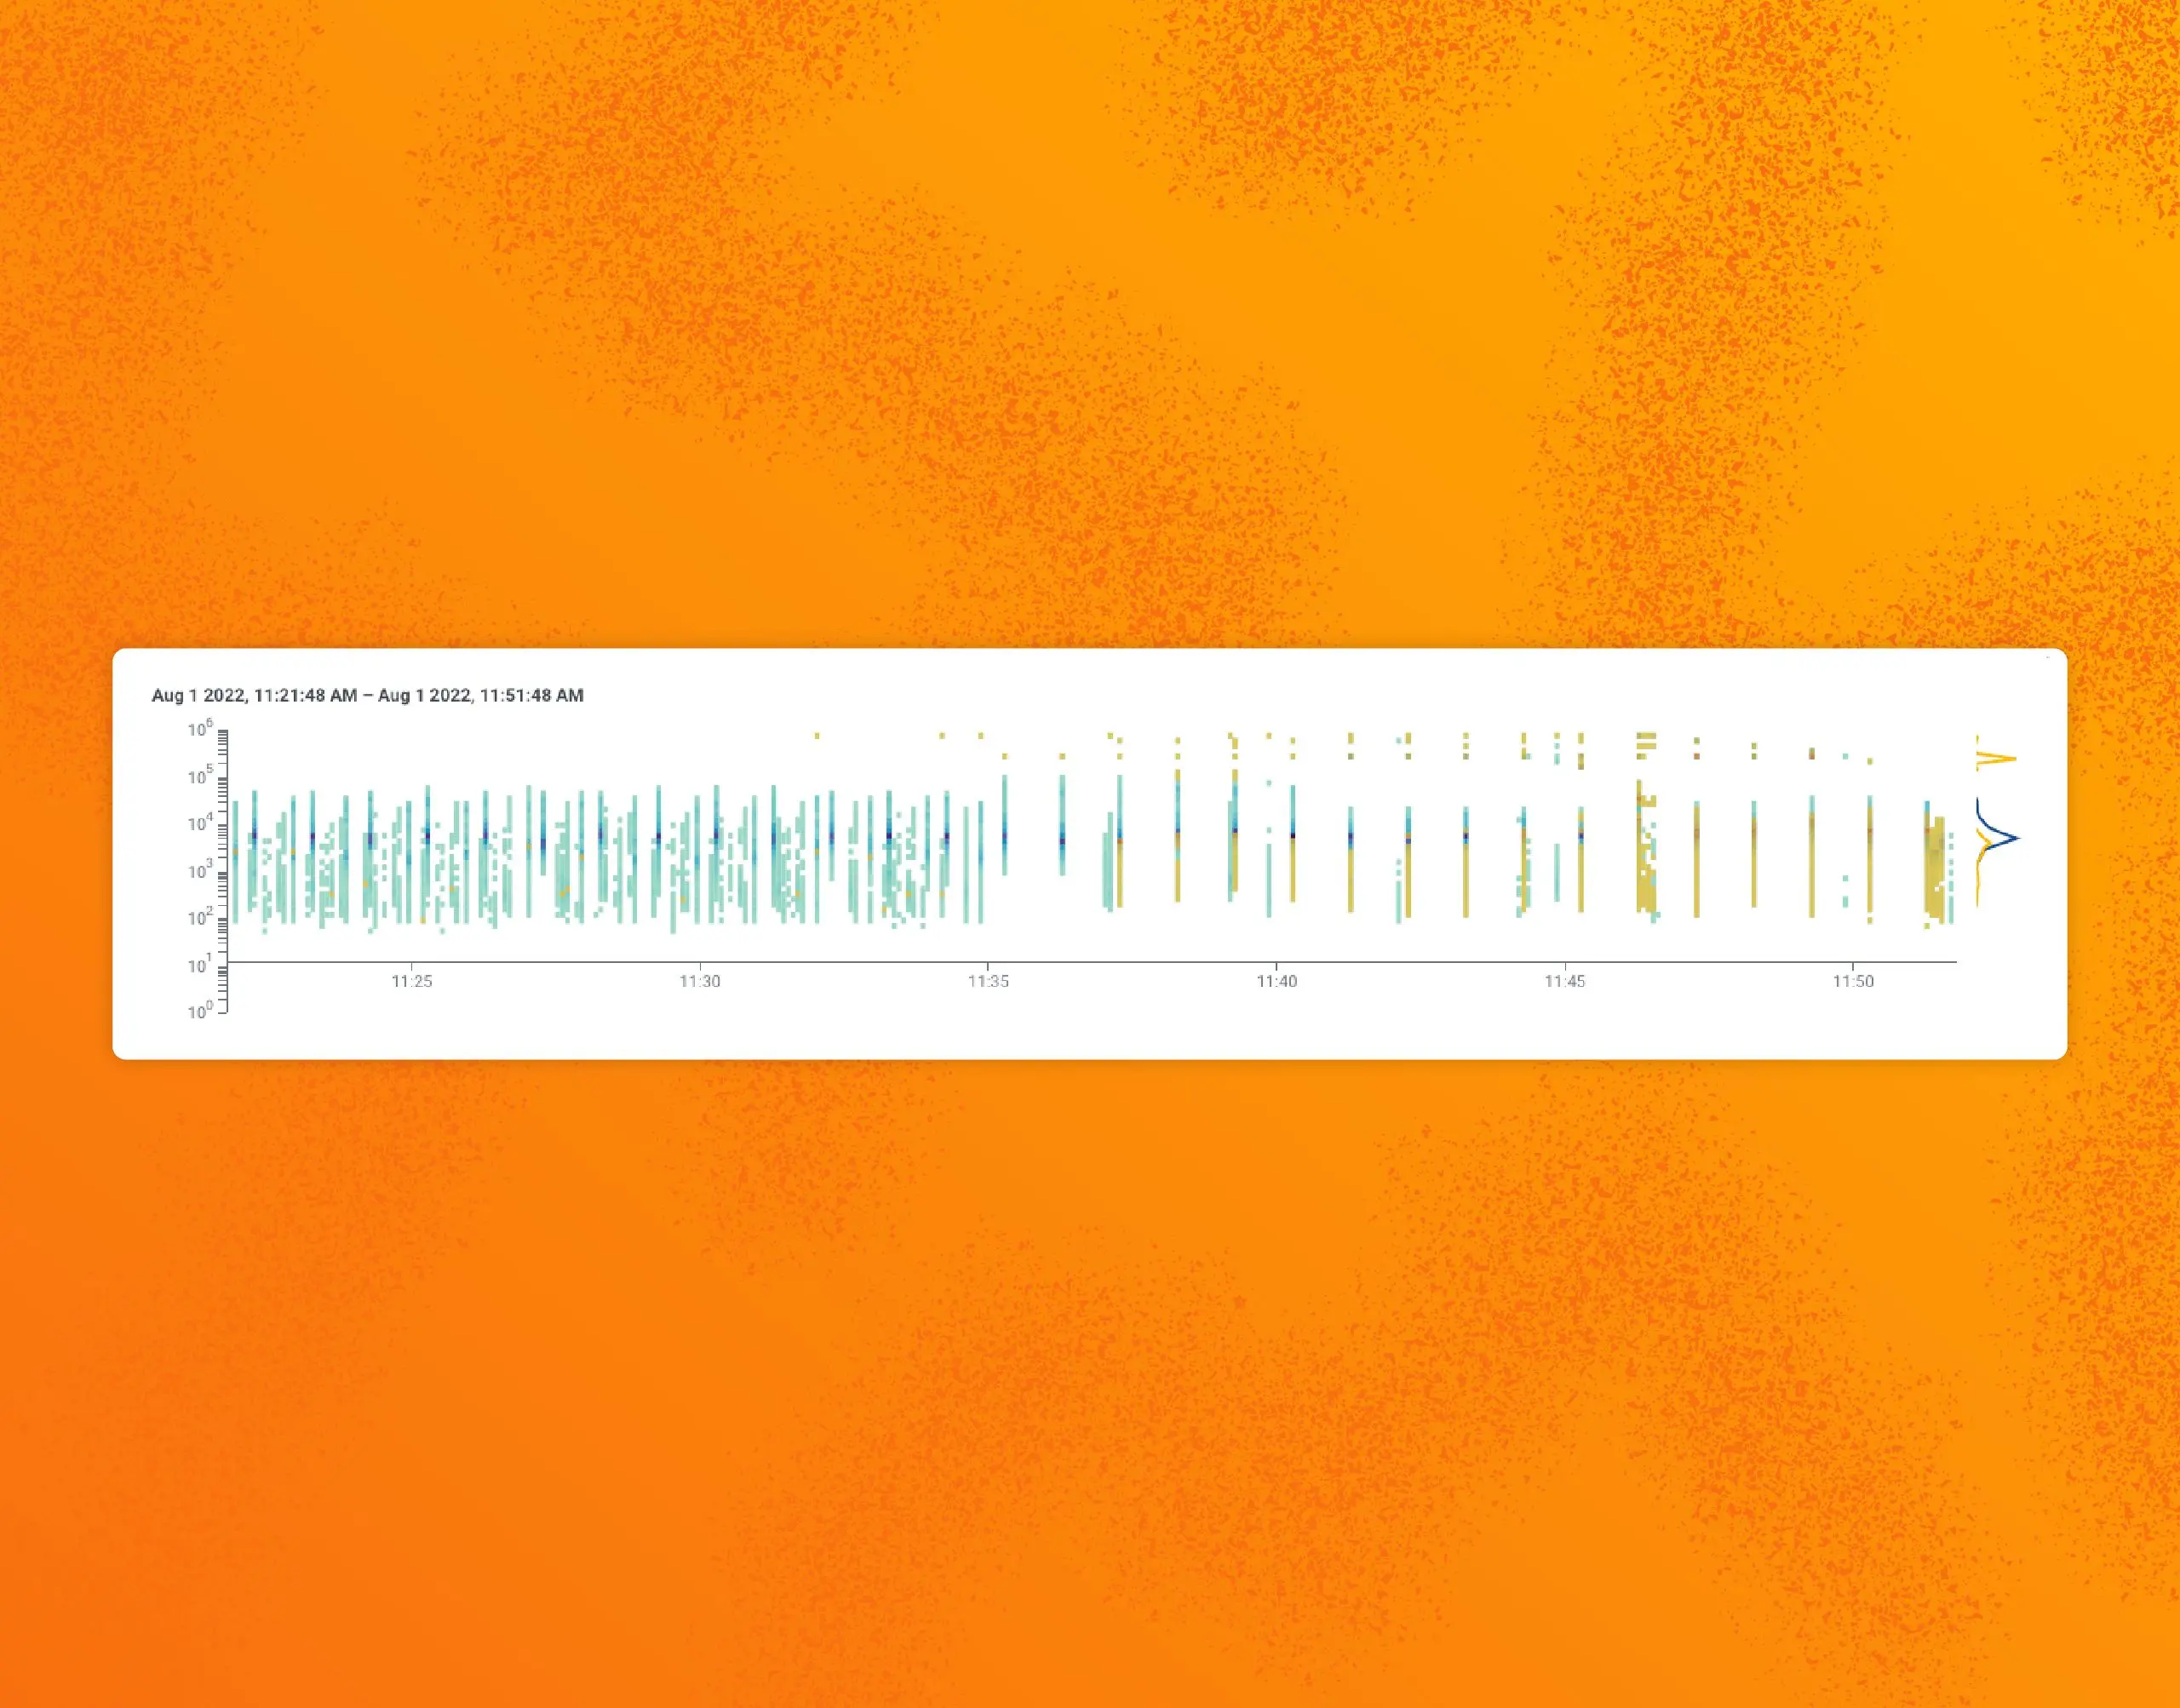
Incident Review: Working as Designed, But Still Failing
A few weeks ago, we had a couple of incidents that ended up impacting query performance and alerting via triggers and SLOs. These incidents were notable because of how challenging their investigation turned out to be. In this review, we’ll go over interesting patterns associated with growth, and complex systems—and how these patterns challenged our operations.
On Counting Alerts
A while ago, I wrote about how we track on-call health, and I heard from various people about how “expecting to be woken up” can be extremely unhealthy, or how tracking the number of disruptions would actually be useful. I took that feedback to heart and wanted to address the issues they raised, and also provide some numbers that explain the position I took with these metrics.
Incident Resolution: Do You Remember, the Twenty Fires of September?
From September to early October, Honeycomb declared five public incidents. Internally, the whole month was part of a broader operational burden, where over 20 different issues interrupted normal work. A fraction of them had…